ICTAI 2026 Accepted
Continuous Retrieval-Grounded Reward Design for Secure Code Generation on Small Language Models (CARGO)
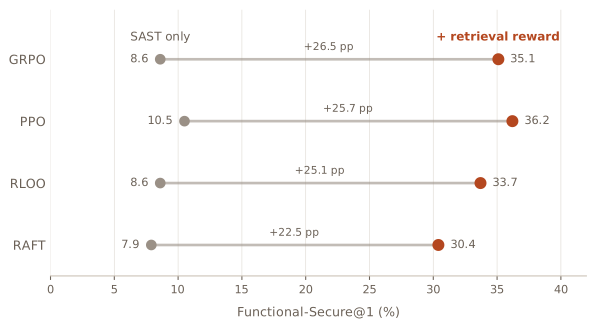
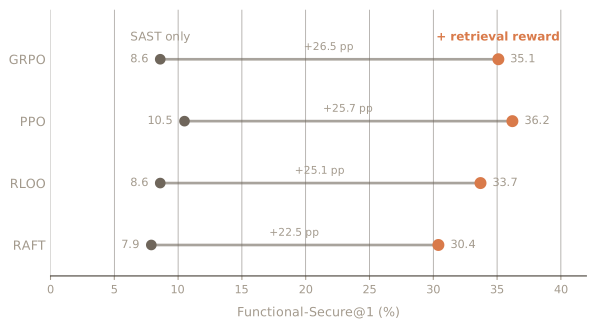
Small code models trained on security-scanner verdicts stall because nearly every early attempt scores the same zero, so this also scores each attempt against a retrieved secure fix to give training something to climb.